A
Track A — Open Source Models & AI Infra
The main track and main-stage story. Covers open models, inference engines, local deployment, platform APIs, evals, tooling, and production reliability.
Open models. Real infrastructure. Physical AI.
Technical talks and demos with the people behind Microsoft Core AI, World Labs, Google Gemini, HeyGen and more. Meet builders from China and around the world, compare approaches and find your next collaborator.
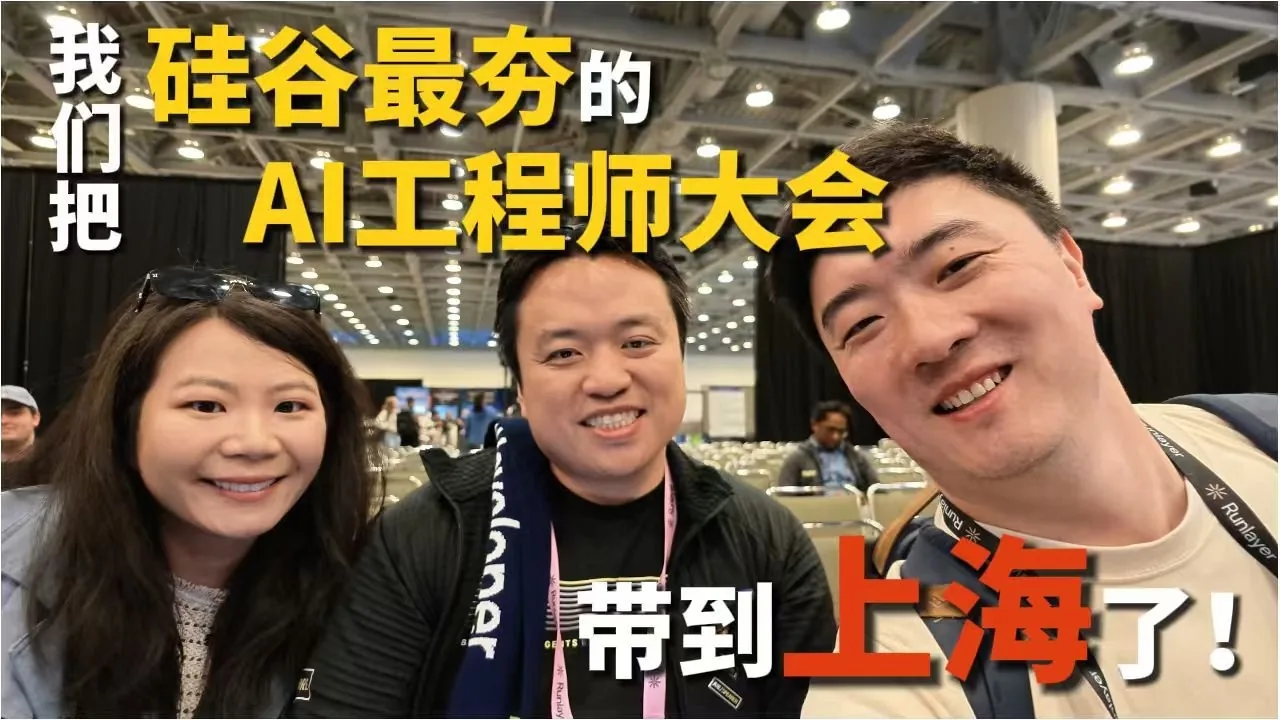
Shanghai organizers: Mengying Li (Standup Partners)Yuzheng Sun, PhD (Superlinear Academy)
AI Engineer brings engineers, researchers and founders together to share how their systems work: code, demos, architecture choices and lessons from production.
Shanghai brings that format to open models, AI infrastructure and physical AI. Meet people building in different ecosystems, compare approaches, and continue the conversation between sessions.
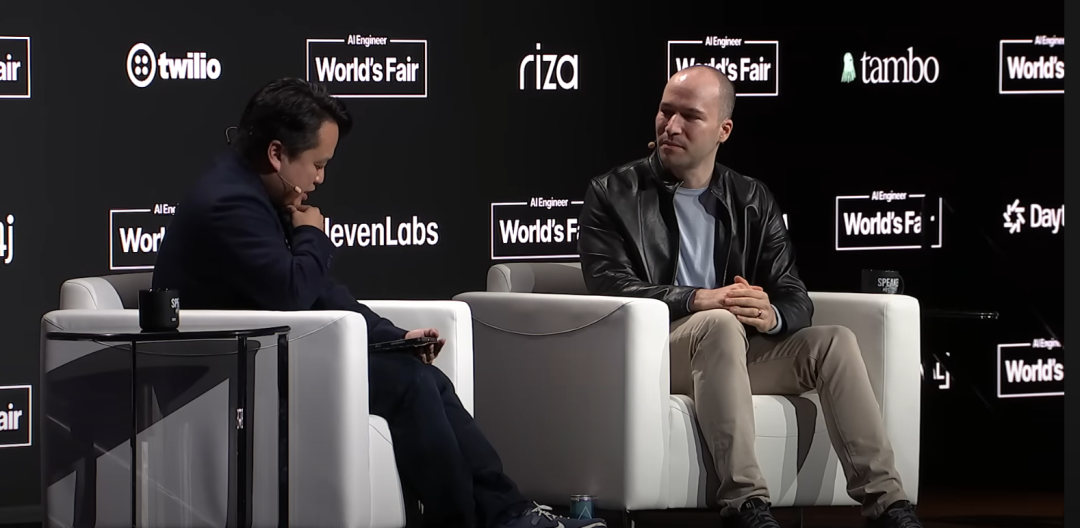
From past AI Engineer flagship events
The main track and main-stage story. Covers open models, inference engines, local deployment, platform APIs, evals, tooling, and production reliability.
The second engineering frontier. Covers VLA / robot foundation models, robot data, simulation and Sim2Real, robot inference, deployment, safety, and real demos. Connects back to Track A: what changes when inference, evals, and deployment move from software into the physical world?
Prepared talks, demos and focused rapid-fire sessions. An AI applications breakout runs alongside the main stage on the first afternoon; day two brings everyone back to one stage.
Tentative: talk titles, formats, day assignments and timings may change.
November 5 opening · 30 minutes
Engineering perspectives from Microsoft, Baseten and You.com.
Development environments and production infrastructure, followed by model-efficiency and AI-coding rapid fires.
YouMind, Harvey, Dify and more on adoption, interaction and reliable delivery.
Generative video, agent design, real-time voice and evaluation.
First after lunch · Conversation
Moderator: Bibi
Proposed discussion focus · Final details to follow
MiniMax and embodied AI teams, then rapid fires on world generation, on-device models and production systems.
Tools, permissions, harnesses, memory and the systems that keep agents working.
How models, data, tools and execution boundaries come together in a useful enterprise workflow, and what changes when an agent moves from a demo into ongoing use.
Teams are reaching for Kubernetes to run agent sandboxes, and it's the wrong tool. Kubernetes is built to keep things alive and hold them in a steady state. A sandbox is born, forked, and killed before any of that machinery catches up. The mismatch compounds because the sandbox keeps gaining requirements without shedding any. In eighteen months it went from a fast code-snippet runner, to a stateful box for long-running agents, to ten thousand ephemeral environments that fork for RL rollouts and die in under a second. It has to be all of those at once, a contradiction set no orchestrator was designed to hold. The cost shows up the moment you measure it. We ran the same 50-action bug-fix trajectory across five stacks and got a 12x spread: 12.9s on the fastest, 161.5s on the slowest. The gap isn't compute, it's lifecycle overhead per action. We name every stack and explain the mechanism behind each number.
The same model can produce very different success rates, costs, latency and risk depending on its agent harness. Drawing on MiniMax Code, this talk examines how tool discovery, cache behavior and execution gates shape those outcomes. Two production examples cover discovering app tools at CLI invocation rather than injecting every tool on every turn, and using file timestamps to prevent writes before reads. The talk also asks which prompts and planning constraints can be removed as models improve, and which boundaries still need to be enforced by the execution layer.
Runtime architecture, tool interfaces, identity and permission boundaries: the practical choices behind open agent systems that can be extended, observed and controlled.
Most teams add AI tools to an old workflow. At Manus, we rebuilt our workflow around agents. We keep all our repositories, team rules, and agent skills in one shared workspace, called Manus mono. Mono connects to almost every service in the company, so an agent can write code, run tests, check logs, work with databases, and ship to production from one place. Because of this, anyone in the company can open a PR. Engineers, product managers, designers, and operations staff all fix the bugs they find. On top of this, every task in our team is visible to everyone. This decouples a task from the person who started it. When a task needs information, you send the link to the person who knows, and the task continues after they answer. When a colleague is away, someone else can take over. Open tasks also give us data on how people actually work with AI. In this talk, I share how we built this way of working, what went wrong, and how it changed the way our team collaborates.
Getting your first AI application into production is hard; you hear that at every AI conference. But what happens when you're managing your 50th, 100th, or 500th agent? At enterprise scale, the challenges fundamentally change. It's no longer just about building agents that work. It's about managing hundreds of agents across teams, business processes, and systems while maintaining reliability, governance, visibility, and control. Who owns each agent? How do you monitor quality and performance? How do you prevent duplicated efforts, manage shared knowledge, and ensure that an expanding AI workforce remains trustworthy? Drawing on real-world enterprise deployments on Dify's AI Agent Management Platform, Andy Wang will explore what happens after AI agents successfully reach production. Topics such as the architectural decisions, operational challenges, and organizational lessons that rarely come up in conversations about pilots, but become impossible to ignore once you approach scale. The next frontier of enterprise AI isn't about how fast you build your first agent. It's about how effectively you manage your next 500.
For the past year, our team has worked the way many teams are about to: each engineer driving a fleet of coding agents, with a shared memory layer underneath doing the remembering. This talk is the engineering report from that year, organized around one question: how much of your judgment can you formalize into environments and verifiers? Whatever stays informal, a human has to stay in the loop to provide. The question plays out at three scales. Personal: which 90% of conversations not to remember, and why forgetting is a feature, not a bug. Loop: self-improvement is bottlenecked by verification, not generation. Where the verifier is deterministic, the loop closes (DeepMind’s AlphaEvolve on Borg scheduling: a discovered heuristic, in production over a year, continuously recovering 0.7% of Google’s fleet-wide compute). Where the verifier is taste, humans hold the merge (Meta’s TestGen-LLM: three mechanical filters first, then engineers accept 73% of what remains). Organization: at night, human review bandwidth is zero, so what your agents can safely do overnight is exactly the judgment you have formalized. That, not model choice, sets the ceiling. Intelligence can be rented. Memory must be owned.
Over the past year we modernized ATLAS end to end, backend and frontend alike: the cohort design workbench the OHDSI medical research network has run for over a decade. The Java backend moved from Java 8 to Java 21 and Spring Boot 3: some 1,600 files, with a net 65,000 lines removed. The frontend is a ground-up rewrite in Vue 3 and TypeScript: 110k lines of source, gated on every pull request by coverage-enforced unit suites and an end-to-end fidelity check against the entire OHDSI Phenotype Library, running publicly at atlas-preview.ohdsi.org/atlas. The large majority of that code was written by coding agents, far more change than anyone could have read line by line. The platform and the verification harness are open source under the OHDSI GitHub org, end to end. On the frontend rewrite I directed, reviewed, and accepted every change. When acceptance cannot mean reading every line, verification has to live somewhere else. The harness became the first reviewer, and I will show what it is made of: specs as the unit of delegation, the legacy implementation as a behavioral oracle, E2E suites and type gates as the merge criterion, and screenshot-driven iteration in place of pixel opinions. I will walk one real feature end to end and show the failure modes the harness caught, the ones it did not, and what I would gate differently today. This talk is for engineers and leads who need to deliver more than their team can hand-write. You will leave knowing how to structure specs so agents can execute them, which verification gates can replace line review and which cannot, and how to tell whether your project fits this model (rewrites with a reference implementation) or does not. Live instance: atlas-preview.ohdsi.org/atlas. All code: github.com/OHDSI/Atlas3.
Post-training, inference, retrieval, data and the economics of production AI.
Search is part of the agent system, not just a list of links. Explore relevance, freshness, latency and the delivery of useful context for real tasks.
An agent that runs twenty steps doesn't issue one retrieval — it issues dozens, and it writes about as much as it reads. The trace it leaves behind is write-heavy, time-ordered, and queried at three granularities: step, span, trajectory. That's the same shape as an RL rollout store. Not similar to — the same. The model labs hit this two years earlier under different names: semantic dedup, decontamination, hard-negative mining. Agent memory and training data are converging on one set of operators — operational writes and analytical scans over the same data, with no ETL in between. That convergence is why we took Milvus from a vector database to a Vector Lakebase. This talk walks through the workloads that forced the shift, and what the architecture looks like underneath.
AI builders keep asking for capabilities that stretch a database beyond its original boundaries: one database per agent, memory across sessions and state that survives disposable sandboxes. This talk follows the production needs that drove those changes, and the resulting choices around isolation, consistency, recovery and observability.
In this session, You.com’s engineering team will share how we post-trained Nemotron 3.5 Lightning, an open-weight 30B model, to become a stronger agent for web search and browsing, using You.com’s real-time web search API, NeMo Gym, supervised fine-tuning, and reinforcement learning. We’ll walk through the technical approach that enabled the team to iterate rapidly. It lifted accuracy on BrowseComp, a benchmark for agentic web search and browsing, from 37% to 45%, while making the agent more efficient with fewer tool calls. We will cover topics ranging from dataset preparation, supervised fine-tuning, and reinforcement learning to the agent harness and search infrastructure that made fast iteration possible. We’ll end with a blueprint for post-training and improving LLMs on real-world search tasks as well as a look at what’s next. This work was done in collaboration with NVIDIA and CoreWeave.
Every NVIDIA GPU generation since Hopper ships TMA, a dedicated engine that copies whole tiles into shared memory while the cores keep computing. Turn it on for every `torch.compile` kernel and SiLU on GB200 gets 1.8x slower. This talk builds the mental model that explains why: when a kernel is memory-bound, what an async copy needs in order to pay off, and the hardware rules that quietly change your tiling. Then it shows how Inductor can stop guessing and instead race TMA and non-TMA versions of each kernel on first launch, the way it already does for GEMMs, without making compile time worse. You leave knowing which of your kernels TMA can speed up, which it can't, and how to tell from a profile in a minute.
RL post-training for coding and agentic models turns every rollout into a sandbox: a fresh environment with a task image, a few commands, a reward, and teardown. A single training run can need Millions of these per hour across thousands of distinct images, with starts arriving in bursts of hundreds and lifetimes measured in seconds. This talk highlights what we learned running 1M sandboxes using an open-source harness on top of Kubernetes called Substrate, and all the various technological innovations in the stack - warm pooling, image acceleration, low latency scalable storage,microVMs, gVisor, golden snapshot and more. We cover the complete stack orchestration layers that make this work in state of the art Al labs including benchmarks and latency assessment.
How can useful AI run directly on phones, PCs and other personal devices rather than depending on the cloud? This talk explores memory bottlenecks in on-device models, using early expert routing and flash streaming to reduce the resident memory footprint. It also covers combining millisecond-scale local decisions with larger on-device models, with examples from headphones, robots and smart glasses.
Open-source model inference is becoming a compelling option for enterprises, especially those building AI-native applications. Delivering fast, efficient, and reliable inference requires engineering across the full stack, from CUDA kernels and Kubernetes orchestration to quantization, caching, and disaggregation. This talk explores the key design decisions and emerging techniques shaping production inference systems, with practical insights into balancing latency, throughput, cost, and reliability.
Jina Reader turns web pages and documents into context models can use. This talk follows its production architecture through dynamic rendering, noisy content, long PDFs and high-concurrency failures, showing the trade-offs between cost, structure and meaning.
Most enterprise AI agent failures don't look like model failures. The model is fine. It just doesn't know which of four revenue tables finance actually uses, who owns it, whether last night's pipeline ran, or that one column was deprecated in March. That knowledge exists inside the organization - scattered across technical schemas, pipeline telemetry, business definitions, and org charts - and almost none of it reaches the agent. This talk is about assembling those four kinds of metadata into a single, model-agnostic context layer that agents can query, and what it actually takes to do that inside a large enterprise. I'll cover the architecture briefly, then spend most of the time on the parts that are harder than the architecture: deciding what context is trustworthy enough to serve, keeping it fresh, exposing it to agents over MCP, and the organizational work of getting teams to maintain context they never see themselves using.
* Semantic Layer as Infrastructure for Data Agents * Apache Ossie: Starting from Metric Interchange * From Specification to Implementation * What Makes a Semantic Layer AI-Native? * Ontology on Top of Semantic Models * Datus + Dosi: Building Semantic Layers and Ontologies from Enterprise Context * An Open Semantic Layer for the Agentic Data Stack
The LLM gateway has become a critical piece of infrastructure at Optiver. Engineers, researchers and agents rely on it daily for a variety of tasks, from analysing large volumes of market news and research to running automated workflows. When the gateway goes down, the impact is expensive and quickly noticed. Keeping LLM traffic running reliably across multiple regions and providers has been challenging, with many of the failures outside our control. In this talk, we share our experience building and scaling a multi-region LLM gateway. We walk through the key design decisions behind protocol translation, scaling, provider failover, observability and multi-region high availability, as well as the tradeoffs and footguns we encountered along the way.
Enterprises buy LLM inference through three structurally different pricing models: credit-based subscriptions, pay-per-token APIs, and self-hosted GPU capacity, with little guidance on which to use at a given volume or what signals it's time to switch. This talk introduces the Efficiency Curve: cost per token under the cheapest procurement mode at each volume, and its crossover points. Using a July-2026 pricing snapshot across three model quality tiers, I show a counter-intuitive finding: the subscription-to-API crossover often never economically materializes; a credit plan's idealized per-token rate can undercut every API price at scale, so the real boundary is a terms-of-service seat limit, not economics. The self-hosting crossover, by contrast, is a genuine price crossover, landing between roughly 360-899M tokens/month depending on tier, and it shifts with output-token share. I walk through the derivation and share a monitoring framework that ties each metric to the procurement decision it should inform, drawn from running AI infrastructure inside a regulated bank.
Real workloads, verification, identity and reliable delivery.
In this session we will discuss the AI eval products and services Arena provides to help frontier model labs and neo labs measure and improve the performance of their models on the global stage.
Recursive self-improvement has moved from Gödel-machine thought experiment to deployed practice. The 2026 industry trends sort these systems along two axes: what the system improves, and how closed the loop is. A system that can rewrite its own definition of "better" is where bounded, convergent self-refinement quietly becomes open-ended RSI and where most published gains stop replicating. This talk maps that literature onto a production system: an automated diagnose–fix–evaluate loop for multi-modal agents. I'll cover where the diagnosis and fix subagents break down, what an attempt memory has to record for a failed fix to be worth keeping, and how to build effective harness.
Every team picking a model right now is reading someone else's leaderboard. We stopped, and the reason was an accident of how we shipped. Harvey released its cloud agent platform to our own engineers before we shipped long-horizon agents to lawyers. Internally it has now driven 7,000+ merged pull requests across our repositories. That internal deployment was not just a safety net — it became the eval set. Once you have thousands of real agent runs on your own workload, you can measure a model against the work you actually do, instead of trusting a public benchmark that was never scored on your tasks. That measurement is what makes it rational to move to an open model, or to fine-tune one, rather than simply hoping it holds up. This talk covers the infrastructure that made that possible, and the four places it broke first: - Durable runs: what happens to a long-horizon agent when the worker dies mid-task, and what we built so the run survives it. - Per-user agent identity: we started on a shared service account and lost the ability to attribute what an agent did. Retrofitting identity was expensive. - Information boundaries: enforcing ethical walls and leaving a reviewable approval trail when an agent acts on a user's behalf. - Context engineering: the case where adding context back made agents measurably worse — a result no external benchmark would ever have surfaced for us. I will show the failures next to the wins, with real numbers and the denominators included, and demo the platform live. Every pattern here is architecture and engineering method, not a product walkthrough.
AI agents are moving beyond reasoning and generation toward taking real-world actions on behalf of users. This shift requires a new infrastructure layer for identity, authorization, trust, credentials, and execution. Drawing on Visa’s work on Visa Intelligent Commerce (VIC), this session explores how these primitives are being designed for autonomous agents — how an agent proves who it is, demonstrates user intent, accesses credentials securely, and interacts with external systems safely. We’ll discuss the emerging infrastructure stack needed to move agents from assistants to trusted actors in the real world.
Turn thousands of your company’s merge requests into benchmarks to improve your coding agent harness.
As one of the founding Android engineers on Instagram Edits, this talk shares my first-hand lessons from making Instagram Edits on Android agentic. Agentic coding has dramatically accelerated development output, but human verification cannot scale at the same rate. We built agentic verification to close that gap. Today, our agents run 2,000+ verification workflows per week across agentic QA, developer feedback loops, stress testing, and debugging. I’ll share how we made a complex mobile app discoverable, controllable, and verifiable by agents, and how that enables a broader agentic mobile development loop that improves both developer velocity and product quality.
AI now writes more than we can check: code, tests, support replies, translations. We used to trust work because a human read it. Nobody can read it all now, and it ships anyway. I hit this in the smallest way possible: I'm building a voice agent that takes bubble tea orders in English and Mandarin. I live in Asia and speak Mandarin every day, like a kindergartener. I can't read or write it. So I can't read half of my own evals. You may read both languages fine. It doesn't help. The volume of changes means nobody reads everything, in any language. Picture what a bad judge costs: Light sugar becomes full sugar, the judge says "pass," and someone gets a bad drink. In a clinic, 十四 (fourteen) sounds like 四十 (forty). The bot hears the wrong dose, the judge says "pass," and someone gets hurt. Multiply that by every call nobody listens to. So I'm building trust as a loop, with Pipecat Evals and open models on one laptop. An LLM writes evals in both languages. A simulated customer orders, switches languages, and changes their mind. A local judge grades the call. Then the loop checks the judge: pass/fail rules I can read, planted bugs the evals must catch, a second judge from a different model family to flag disagreements, and a native speaker for the calls that matter. You'll leave with that loop, and one question for any eval: what would it take for this test to be wrong, and who would notice?
Creative tools, voice, video, interfaces and applications grounded in real industries.
Base models are racing toward AGI, and the real value of an AI application is turning real-economy data into a moat. This session covers how a mapping connects foundation models to industry data, and how that builds a flywheel that's hard to copy. That's how AGI gets put to work in the beauty industry, where the data moat lives. The team pairs brand-side experience with a distinct female perspective, carrying the industry's tacit know-how into the last mile where consumers decide.
Yubo shares how to use YouMind to build a Personal Agent for personal growth.
As agents do more of the work, product interfaces need to make their state, changes and decisions legible. Explore how visibility and human takeover shape useful AI-native products.
general audience version: Most agent output still ends its life as text. We think that's a waste of a rendering engine. This talk shows how treating HTML as an agent's primary output format turns model responses into videos, slide decks, and business artifacts that people can actually use — no bespoke renderer, no proprietary format, just the most widely trained-on markup language in existence. We'll walk through the architecture of an agentic system built around HTML as its visualization layer, what breaks at scale, and what we learned shipping this in production. We'll also introduce HyperFrames, our open-source, free framework for agent-generated visuals, and show how teams can drop it into their own agents today. technical audience version: Multimodal agents fail in ways text-only agents don't: the model can't see what it made, can't reliably locate things in a frame, and can't hold a long visual edit in working memory. This talk covers the context engineering techniques we developed at HeyGen to close that gap — asset naming conventions that carry semantics, contact-sheet and collage prompting for VLM review, frame numbering and grid overlays for spatial grounding, and HTML as an intermediate representation that keeps generation inside the model's training distribution. The underlying thesis: don't fight the distribution, reframe the problem into one the model already knows how to solve. We'll close with HyperFrames, the open-source framework where these techniques live.
The engineering choices behind expressive speech and real-time voice agents: latency, control, deployment and the experience of an actual conversation.
AI is systematically absorbing the technical core of game development. Code generation tools now produce gameplay scripts, shaders, and engine plugins from natural-language prompts, while AI pair-programmers handle debugging, refactoring, and unit tests autonomously. Procedural content pipelines driven by generative models build entire levels, NPC behaviors, and quest logic without manual scripting. Automated QA bots playtest builds around the clock, flagging bugs faster than human testers. Even optimization — memory profiling, performance tuning, cross-platform porting — is increasingly delegated to AI agents. The developer's role shifts from writing code to reviewing, orchestrating, and validating machine output. This paper examines which engineering tasks AI has already displaced and what expertise remains irreplaceably human.
Your website is your worst salesperson—static, unresponsive, and abandoning 78% of potential customers. For 25 years we’ve called it “optimization,” yet all we do is swap Button A for Button B or craft a few account‑level pages, praying for a 2 % bump. Each tweak burns weeks of design and dev time while visitors bail in seconds, conversions stall, and acquisition costs keep rising. Modern traffic is rushing through a testing process built for dial‑up days, and the leak grows every day. Your website could function as your top sales performer—qualifying leads, demonstrating value, getting marketing insights, and closing deals 24/7 without any human intervention. You’ll learn why webpages are bleeding visitors, what turns a site into Web 4.0 Agent—adaptive video, live voice, and on‑screen digital humans working in sync and showing your product. How to bolt those layers on with simple APIs instead of a rebuild, the design moves that hook eight‑second attention spans, the conversion lifts early adopters are already logging, and a clear six‑step pilot plan to bring one high‑value page into this future and then scale it across your entire site.
An LLM is a non-deterministic token machine. A production UI has to be reliable, consistent, and fast every time. Generative UI lives in the gap between those two facts, and that gap is usually treated as a frontend problem when it is really an infrastructure problem. This talk is the engineering story of closing that gap. We started where most teams start: ask the model for JSON, validate it against a schema, and render the tree. It demos well, but breaks down in production. Deeply nested JSON streams slowly, malformed structures appear under load, half-finished objects cannot render, and the output drifts from the design system. I’ll show the reliability layer we built in OpenUI to fix this: a compact, line-oriented language that models emit more reliably than nested JSON; streaming with forward-reference hoisting so each line can render as it arrives; and validation that drops invalid fragments instead of crashing the interface. The result is near-zero malformed output, up to 3x faster rendering, and 67% fewer tokens than JSON in public, re-runnable benchmarks. I’ll also cover the tradeoffs, including where schema-validated JSON and native protocols still make sense.
The Little Prince: Across the Stars is a 3D story game built by one person with AI. This talk follows the project from adapting a familiar story into explorable scenes, through iterating on code, 3D assets and visual polish, to its public launch. Sac shares what worked, what did not, and what the process means for people creating with AI.
Speech-to-text seems like a solved problem. But when we looked at our own Mandarin practice sessions, we found something unexpected: about one in four had words in the transcript that were never spoken. A streaming model was inserting Korean, Hebrew, and Thai into Mandarin answers. We ran the same recordings through the model after the sessions, and the transcripts were almost perfect. The models that struggled with our audio also scored well on public benchmarks. To find out why, we built a replay rig and tested four models on real sessions. We switched the model we used in production, but that still didn’t explain everything. So we kept investigating. I’ll show you what we found, step by step, including the two settings that had the biggest effect on streaming transcription—and how much each one can improve results on your users’ audio.
Spatial intelligence, action models, robot hardware and real-world data.
“World Model” is a ubiquitous - and overloaded - term. Let’s explore how world models are used from simulation to visual understanding in the context of spatial intelligence and beyond.
AI has made rapid progress in language and 2D visual generation, but Physical AI requires something more fundamental: the ability to represent a persistent 3D world, understand how that world changes under actions, and interact with it over time. In this talk, VAST will share its technical evolution from 3D foundation models to world models. We will discuss how 3D generation is moving from high-fidelity visual assets toward native, pipeline-ready spatial representations, and how this spatial foundation can further evolve into persistent and interactive worlds. A key focus will be a world-model architecture that separates world state, state transition, and generative rendering. Rather than predicting only the next video frame, the model maintains a camera-independent 3D state and learns how that state evolves, enabling long-term consistency, controllable interaction, multi-view reuse, and real-time experiences. We will also discuss how internet video and engine-native synthetic data can be transformed into aligned 3D state and action data, providing a scalable path toward simulation and training infrastructure for Physical AI.
In mid-September, the release of Jev kicked off a new category of AI models: decision models. Instead of generating text, a decision model answers bounded questions (which tool to call, which route to take, whether an action is safe) and returns a typed answer with a calibrated confidence. In this talk, we'll cover what decision models are, why everyone is excited about them, and how they work. We'll then share how we're building open, multimodal decision models for the edge on top of our LFM architecture. We'll close with a live demo of a multimodal decision model running fully on-device.
Beyond Vision-Language-Action, the next generation of Physical AI requires a fundamentally different understanding of intelligence. While recent progress in VLA models has significantly improved high-level semantic reasoning and robotic policy learning, physical interaction with the real world remains constrained by limited perception modalities and simplified assumptions about embodiment. This talk revisits Embodied AI from first principles. Inspired by biological cognition and human sensorimotor systems, we discuss why future Physical AI must evolve beyond vision and language toward rich multimodal perception—including force, tactile sensing, proprioception, contact dynamics, and continuous interaction with the physical world. We further propose a layered framework for Physical AI, covering perception, cognition, world modeling, robot foundation models, action generation, data engines, simulation, and lifelong learning. Rather than treating these components independently, we argue that they should form a closed-loop embodied intelligence system capable of continuous adaptation through interaction. Finally, we discuss pragmatic engineering principles for deploying Physical AI in today’s industrial environments, outlining an incremental roadmap from narrowly specialized robotic applications toward more general-purpose embodied intelligence.
This talk introduces Noe-0, Noematrix’s embodied intelligence pretraining model. Its World Action Model jointly predicts future video and robot actions, connecting world understanding with physical execution. We will present our Full-chain Zero-Teleop approach, which uses RoboPocket to collect real-world human manipulation data for both pretraining and task-specific post-training. The talk will cover key model design principles, representative robot demonstrations, and open research questions toward robots that can perform a wider range of everyday tasks.
Robot hardware has traditionally focused on speed, payload, precision, and actuator performance. Yet as robot intelligence rapidly evolves—from imitation learning to VLA models, world models, and end-to-end approaches—hardware must adapt to changing software architectures while remaining reliable over years of deployment. Through the development of Taku, we explore this challenge from three perspectives: Reliable Foundation, Robust Interfaces, and Accelerated Iteration.
Robot datasets grow not only by adding new episodes, but also by accumulating derived columns such as embeddings, labels and rewards as new models become available. Traditional approaches often require rewriting entire datasets and depend on fragile job orchestration. This talk applies build-system ideas to robot data: precisely tracking work that has not yet been computed, incrementally processing missing ranges, resuming interrupted jobs, atomically publishing results, and pinning data versions for reproducible training. With LanceDB, teams can continually update a robot’s understanding of historical data without repeatedly rewriting the raw data.
Exploring the Real2Real paradigm and Quantum Boltzmann Machines for sampling optimal behaviors grounded in real-world embodied intelligent agents.
Located in Shanghai’s Hongqiao business district, the Hilton Shanghai Hongqiao is a five-star hotel designed for international business events and conferences. Just a short drive from Hongqiao International Airport and the National Exhibition and Convention Center (NECC), the hotel features spacious ballrooms, state-of-the-art meeting facilities, and luxury accommodations. Its convenient location and conference facilities make it a premier venue for global business and technology events.
Check out the hotel →
Thank you to the sponsors and partners supporting AI Engineer Shanghai.
Organizations helping make this event possible.
 Superlinear Academy
 Adyen
 QuantSparkle.ai
 AutoArk
 MiniMaxautotrust.ai
 Linkloud
 WaytoAGI
November 4 · 18:00–20:30 · Shanghai time
Meet builders before the conference for talks on agent infrastructure and an evening of conversation, with pizza and drinks.
Separate free registration, subject to host approval. Location shared by the host after registration.
View event & apply on Luma ↗US citizens are not on China’s 30-day visa-free list, but there are two good options depending on your travel route:
Citizens of 35 European countries (France, Germany, Italy, Netherlands, Spain, UK, Switzerland, and more) enjoy 30-day visa-free entry to China until December 31, 2026. No advance visa application needed. Just arrive with a valid passport.
Covers tourism, business, and transit. Full list includes all major EU/EEA countries plus the UK, Switzerland, and Norway.
Fill out the Visa Letter Request Form here after booking your ticket, and take the generated document to your local consulate to apply for your China entry visa.
Visa policies can change quickly. Regardless of your nationality, please confirm your specific requirements, local consulate locations, and the most up-to-date documentation checklists via the official Chinese Visa Application Service Center Portal (www.visaforchina.cn).
A recent global AI Engineer livestream while Shanghai-specific programming is finalized.
A prior flagship recording from the AI Engineer channel.
Choose your preferred checkout. Ticket types, prices and any applicable offers are shown on each booking page.
The Shanghai edition is organized by Standup Partners, working with AIE and local partner Arogo Intelligence. Mengying Li and Yuzheng Sun bring together speaker relationships, program development and communities across the US and China.
Mengying has led growth and data work at Braintrust, Notion and MotherDuck. At Standup Partners, she advises AI and developer-tool companies on growth and cross-border expansion. For AIE Shanghai, she leads international partnerships and speaker relationships.
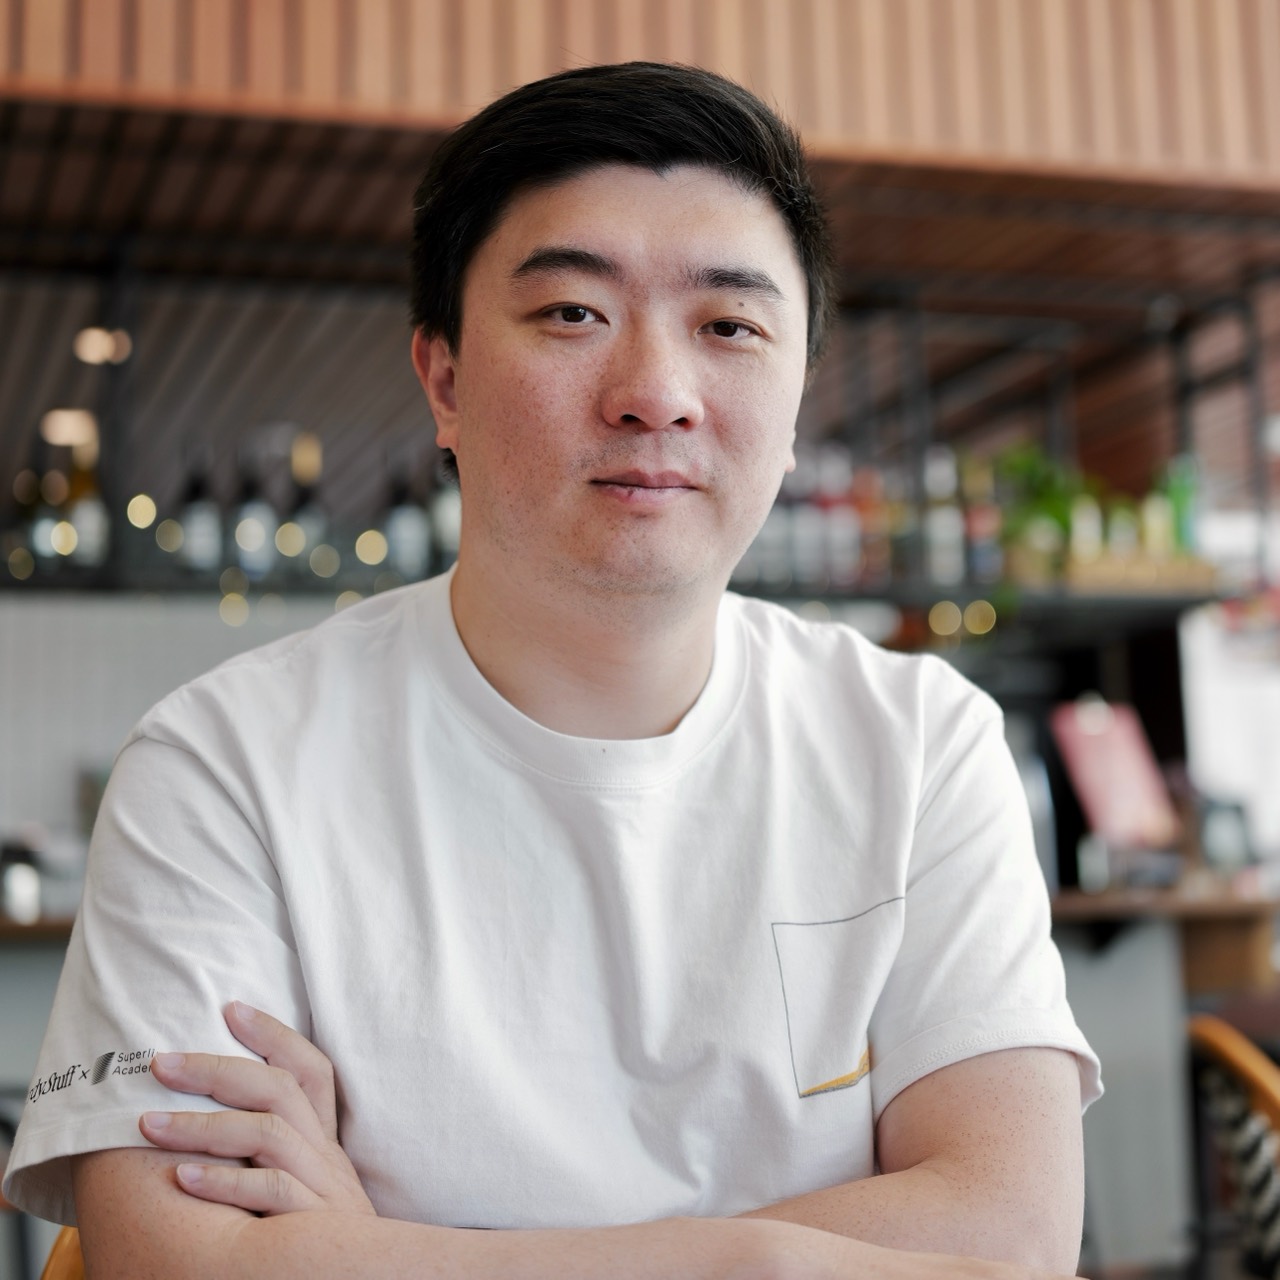
Founder of Superlinear Academy with a PhD in Economics from Cornell. He previously served as Vice Director of Data and Growth at Tencent, a data scientist at Meta, an economist at Amazon, and an early team member at Statsig (later acquired by OpenAI). He has hosted more than 200 conversations with researchers, founders and practitioners. For AIE Shanghai, he shapes the program, invites speakers and connects builder communities.
Shanghai organizer: Standup Partners · Local partner: Arogo Intelligence




 ClickHouse




 Haier Global AI Research Institute